Find Mispriced MMA Bets with a Verified MMA Betting Model
An MMA betting model is a machine learning system that converts fighter stats, style matchups, and market data into calibrated win, method, and round probabilities. Used correctly, it can help you find bets where the sportsbook’s price is off by a meaningful margin. It cannot beat the market outright. The strongest versions blend three signal types: quantitative fight stats, betting-market odds, and expert or sentiment consensus, then check every output against real money lines before you risk money.
TL;DR:
- An MMA betting model needs to produce probabilities for multiple outcomes, such as win chance, method, and round, with proper calibration for accuracy.
- Data should be clean, sourced from multiple platforms, and features engineered using recent form, style matchups, and context flags like injuries or camp changes, retrained after each UFC event.
- Gradient-boosted trees like XGBoost or LightGBM are proven models, with ensemble stacking and proper backtesting on chronological splits to avoid leakage and overfitting.
- Comparing model probabilities to sportsbook implied probabilities and applying positive edge thresholds are essential before placing bets, with line shopping and tracking closing line value.
- Recognize the limitations of models in capturing variance, recent form shifts, and late-notice changes, and always bet only what you can afford to lose with disciplined bankroll management.
Table of Contents
- Building an MMA Prediction Model: What It Needs to Get Right
- What Data and Features Go Into an MMA Betting Strategy
- Which Machine Learning Models Work Best for MMA Predictions
- How to Evaluate and Backtest an MMA Betting Model Before Risking Money
- Turning Model Probabilities Into Actual MMA Bets
- Where MMA Betting Models Fall Short
- How Manny’s Variety Validates Its Predictive Engines
- Why Rare Fight Outcomes Need Special Handling
- Accounting for Injuries, Camp Changes, and Fight-Week Psychology
- Keeping an MMA Model Current With Live Fight Data
- Making Model Predictions Explainable
- Managing an MMA Betting Portfolio Like a Real Book
- What Builders and Bettors Get Wrong
- Get a Verified MMA Betting Model Without Building One Yourself
- Sources
- FAQ
Building an MMA Prediction Model: What It Needs to Get Right
A usable MMA prediction model has to output more than a coin-flip guess on who wins. It needs probabilities across several markets at once.
- Moneyline probability — win likelihood for each fighter
- Method of victory — knockout, submission, or decision splits
- Round or time bucket — early finish versus going the distance
- Fight duration — a regression estimate feeding total-round props
What matters is calibration: when the model says a fighter has a 70% chance to win, that fighter should win close to 70% of the time across a large sample. That’s why serious builds are graded on log loss and Brier score rather than raw hit rate. The realistic ceiling, per methodology published by CageMetrics, puts well-built classifiers in the mid-to-60s accuracy range on held-out fights, closing much of the gap to the market’s own closing-line accuracy without routinely beating it.
What Data and Features Go Into an MMA Betting Strategy
Every serious MMA betting strategy starts with clean, well-sourced fight data tied to a single fighter ID across their whole career, not a new record every time they change management or promotions.
- UFCStats for granular strike, grappling, and control-time data per round
- Sherdog and Tapology for career records, camp history, and non-UFC results
- Odds feeds from multiple sportsbooks for opening and closing lines
Feature engineering is where most of the real work happens. Rolling stats using an exponentially weighted moving average (EWMA) capture recent form better than career averages. Style-matchup ratios (grappler versus striker, output rate deltas) and stamina or fatigue modeling based on fight pace and layoff length round out the picture, along with reach and height deltas and flags for short-notice fights or weigh-in issues.
Build features chronologically, using only information available before the fight date, and decide early how you’ll handle fighters with sparse pre-UFC records rather than letting the model treat missing history as zero. Retrain on a regular schedule, ideally after every UFC card, since roster turnover and rule tweaks shift the underlying distribution faster than most other sports.
Pro Tip: Store every rolling-window calculation with a timestamp. If you ever need to debug a leak, being able to reconstruct exactly what the model “knew” on a given date saves hours.
Which Machine Learning Models Work Best for MMA Predictions
Gradient-boosted trees remain the practical baseline for most builders. XGBoost and LightGBM handle tabular fight stats well, train fast on GPU, and give you SHAP-based feature importance almost for free. Neural embeddings get layered on top when you want the model to learn fighter style representations directly from historical matchups rather than hand-coded ratios, though embeddings need enough per-fighter history to be worth the added noise.
A production-grade setup typically stacks several base models and feeds their outputs into a logistic regression meta-learner, which then gets calibrated separately. One publicly documented example combining quantitative stats, NLP sentiment, and expert consensus in a GPU-accelerated ensemble reported roughly 78% accuracy and a 0.87 ROC-AUC on its own dataset. That’s a strong result on that specific sample, not a promise of what any model will do against live sportsbook pricing.
Common architecture choices include:
- XGBoost or LightGBM as base learners with GPU acceleration for faster retraining cycles
- A logistic meta-learner combining base model outputs into one calibrated probability
- Separate handling or exclusion of fighters with fewer than three or four tracked fights, since low-history embeddings tend to add noise rather than signal
How to Evaluate and Backtest an MMA Betting Model Before Risking Money
Chronological splits are non-negotiable. Train on fights before a cutoff date, test on everything after it, and apply a minimum-prior filter so the model isn’t scored on fighters it has almost no history for. Skip this and you’ll get leakage that inflates every metric you look at.
- Prioritize log loss and Brier score over raw accuracy, since both punish overconfident wrong calls harder than a simple hit rate does
- Check ROC-AUC as a secondary measure of how well the model ranks fights by win likelihood
- Plot predicted probability against actual outcome frequency, then apply Platt scaling or temperature scaling if the curve bends away from the diagonal
- Backtest the resulting bets against the closing line, not the opening line, to isolate real predictive edge from market drift
The CageMetrics methodology documents a 37-feature gradient-boosted classifier benchmarked this way against both Elo and market baselines. A separate line of academic work using Markov chain models for MMA forecasting backs the case that formally modeling fight dynamics, rather than eyeballing stat sheets, produces statistically meaningful predictive power. Run Monte Carlo simulations across your bet history to see the range of bankroll outcomes your edge actually implies, not just the average.
Turning Model Probabilities Into Actual MMA Bets
A probability output is worthless until you compare it to what the sportsbook is implying with its price.
- Convert the moneyline to implied probability (for American odds of +150, that’s 100 divided by 250, or 40%)
- Compare your model’s probability to that implied number and set a minimum edge cutoff, commonly 5 percentage points or more, before you consider a bet
- Size the bet conservatively: flat staking at 1 to 3% of bankroll, or a fractional Kelly criterion scaled down to reduce variance
- Shop the line across multiple sportsbooks before placing anything, and log the closing line so you can calculate closing-line value (CLV) later
Undercard fights, method-of-victory props, and round props tend to carry softer pricing than main-event moneylines, since sharp bettors and syndicates focus their attention on marquee cards, leaving undercard lines less efficiently priced. Live in-play markets add another layer of opportunity for models that can update mid-fight, though that requires faster infrastructure than a pre-fight-only pipeline.
Pro Tip: Track CLV religiously. Beating the closing line consistently over a rolling 100-bet sample is one of the few honest signals that your edge is real and not just variance.
Where MMA Betting Models Fall Short
No model captures everything a fight involves, and pretending otherwise is how bettors blow up bankrolls.
- Single-event combat sports carry enormous variance. A single strike can end a fight your model gave 80% to the other side.
- Concept drift is constant: rule changes, judging trends, and roster shifts move faster in MMA than in most team sports.
- Data errors and late-notice opponent changes can quietly corrupt a feature set built on the wrong fighter.
- Overfitting on a small historical sample is easy given how few MMA fights exist compared to other sports’ box scores.
Bet only with money you can afford to lose, set firm stake limits before the card starts, and treat any model as one input among several. If gambling stops feeling optional, BeGambleAware offers free, confidential support.
How Manny’s Variety Validates Its Predictive Engines
Manny’s Variety publishes every pick in a permanent, publicly graded archive rather than deleting misses, which is the first thing worth checking on any vendor. Its claimed 63.5% win rate and 443.9-unit net return are backed by that same archive of MMA and UFC picks. Before trusting any service, confirm three things: a visible track record, a stated evaluation methodology, and calibration behavior you can actually inspect rather than take on faith.
Why Rare Fight Outcomes Need Special Handling
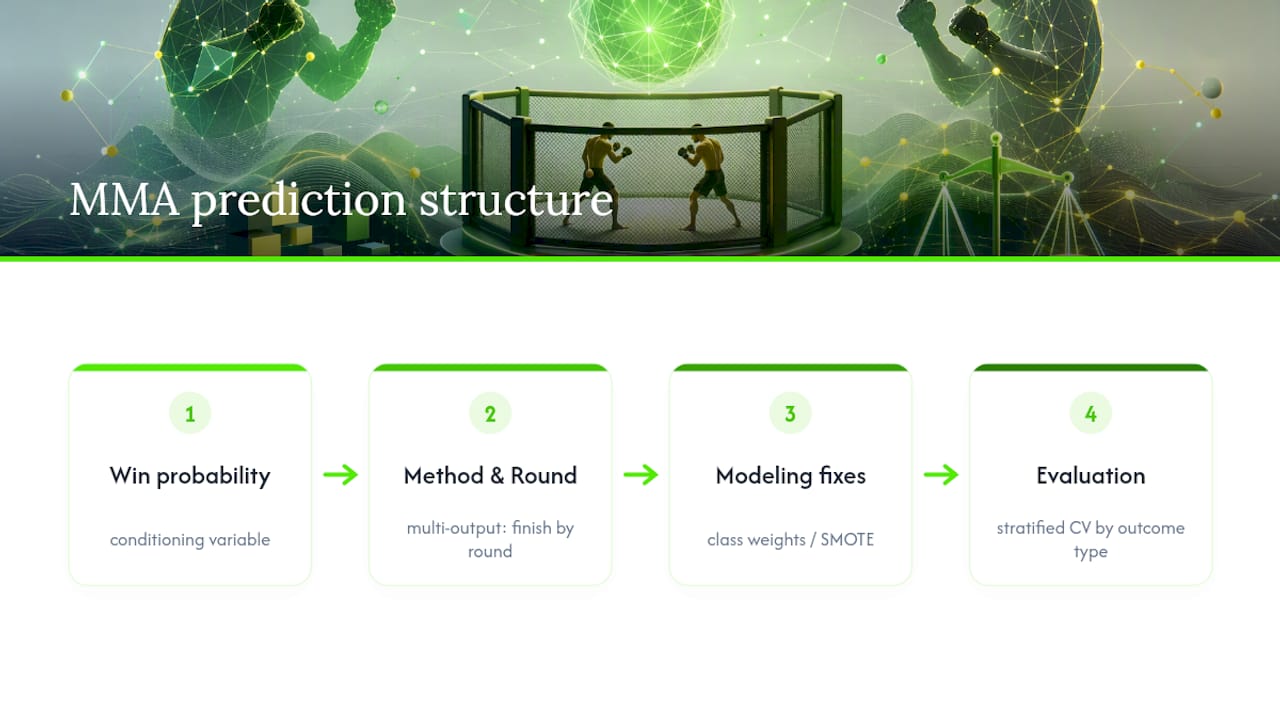
Finishes by submission in the first round, or upsets by heavy underdogs, occur far less often in the training data than decisions or favorite wins. A model trained on raw frequencies will systematically underpredict these rare outcomes, which happens to be exactly where the mispriced betting value tends to live.
The standard fixes borrow from broader rare-event machine learning. Class weighting inside XGBoost or LightGBM penalizes the model more heavily for missing a minority-class outcome (like a first-round finish) than for missing a common one. Oversampling techniques like SMOTE can help for smaller datasets, though synthetic fight data has obvious limits since you can’t meaningfully interpolate between two real fighters’ stat lines.
A cleaner approach for MMA specifically is to model method and round as a separate multi-output problem rather than folding everything into one win/loss classifier. Predicting “finish probability by round” as its own regression or ordinal target, conditioned on the win probability, tends to produce better-calibrated prop odds than trying to force one model to handle moneyline and method simultaneously. Stratified cross-validation, split by outcome type rather than random shuffling, also keeps your evaluation honest when one class (say, decisions, which make up the bulk of UFC outcomes) dominates the sample.
Underdog wins land in roughly 28 to 32% of UFC fights, which is common enough that a model ignoring this segment is leaving real value on the table, but rare enough that naive training will still underweight it without deliberate correction.
Accounting for Injuries, Camp Changes, and Fight-Week Psychology
Stats alone miss a huge share of what actually decides a fight. A fighter switching camps six weeks out, training with a new head coach, or coming off a documented injury layoff carries real predictive weight that rolling averages simply can’t see.
The practical fix is a set of binary and categorical flag features layered onto your core stats: camp change in the last training cycle, short-notice replacement opponent, weight-cut history and any missed weigh-ins, and documented injury or extended layoff. These flags rarely carry huge weight individually, but in aggregate they shift a model’s confidence meaningfully, particularly for fighters already near a 50/50 line.
Psychological and momentum factors are harder to quantify and easy to overweight. NLP sentiment models scanning fighter interviews, media coverage volume, and camp reports can surface momentum signals, but this data is noisy and vulnerable to promotional hype cycles inflating sentiment ahead of a pay-per-view card. The practical approach is to blend sentiment in at a deliberately low weight initially, adjusting for article volume and volatility rather than treating every mention as equal signal, and let backtesting tell you whether that signal earns a larger role over time.
None of these context flags replace the quantitative core of the model. They’re a correction layer, applied after the base prediction, that nudges probabilities toward what a sharp human handicapper would already suspect watching fight-week media.
Keeping an MMA Model Current With Live Fight Data
MMA doesn’t sit still between events the way a full baseball season does. A model trained six months ago is working with stale rankings, missed layoffs, and fighters who’ve since changed weight classes entirely.
Treat the fighter population as a rolling time series rather than a fixed dataset. Every EWMA-based feature should update the moment new fight data lands, and a full retrain should follow every UFC event rather than sitting on a quarterly or seasonal schedule most other sports models can get away with. That cadence matters more in MMA than in team sports because a single roster is small: one new data point genuinely shifts a fighter’s rolling profile.
Live, in-fight updating is a separate and harder problem. Round-by-round strike and control-time data can feed a model that recalculates win probability between rounds, which is the same infrastructure behind live in-game betting products. Doing this well requires a low-latency data feed, a model architecture that can run inference in milliseconds rather than seconds, and a fallback plan for when the data feed lags behind what’s happening in the cage.
GPU inference matters here in a way it doesn’t for a once-a-week pre-fight batch job. A stacked ensemble that takes two seconds to score a single fight pre-fight is unusable for live betting, where the number line moves round to round. Most practical builds solve this by running the heavier neural components pre-fight only, then swapping to a lighter gradient-boosted model with fewer features for the in-play recalculation, trading some accuracy for the speed live markets demand.
Making Model Predictions Explainable
A win probability with no explanation behind it is hard to trust and even harder to debug when it’s wrong. SHAP (SHapley Additive exPlanations) values solve this for tree-based models like XGBoost and LightGBM by breaking down exactly how much each feature pushed a given prediction up or down from the baseline.
In practice, this means you can look at a specific fight and see that reach advantage contributed +4 percentage points to Fighter A’s win probability, recent finish rate contributed +6, and a short-notice flag on Fighter B contributed another +3, all summing to the final output. That level of detail does two things a black-box score never can: it lets you catch a feature behaving strangely (say, a data entry error inflating one fighter’s strike stats), and it lets you sanity-check the model against your own fight knowledge before you bet on its output.
Feature importance plots, aggregated across many fights rather than a single card, also confirm whether the model is actually learning something sensible. If a model built to predict method of victory is leaning heavily on a feature like fighter nickname length, that’s a signal something in the pipeline is broken, not a hidden pattern worth trusting.
For neural network components layered into an ensemble, interpretability gets harder, which is one honest argument for keeping gradient-boosted trees as the dominant piece of the stack rather than leaning entirely on deep learning. A meta-learner combining multiple base models adds one more layer worth inspecting: check whether it’s assigning sensible weight to each base model rather than letting one noisy component dominate the blend.
Managing an MMA Betting Portfolio Like a Real Book
Treating each fight as an isolated bet is how disciplined bankrolls turn into undisciplined ones. A full UFC card might offer fifteen or more betting opportunities across moneylines, props, and parlays, and staking each one independently without a portfolio view means correlated risk sneaks in unnoticed.
Correlation is the first thing to manage. A method-of-victory prop and the moneyline on the same fight aren’t independent bets. If you’re already exposed to a fighter winning via the moneyline, stacking a same-fighter finish prop on top multiplies your exposure to one outcome rather than diversifying it.
Set a hard cap on total card exposure, commonly 5 to 10% of bankroll across every bet combined, regardless of how many individually attractive edges the model surfaces. Reserve a bigger chunk of your flat-stake or Kelly sizing for higher-confidence main-card fights with deeper fighter history, and cut stakes on short-notice or low-data fights even when the model’s edge estimate looks large, since that edge is built on thinner information.
Running periodic Monte Carlo simulations across your full bet history, rather than just single-bet projections, shows you the realistic range of bankroll outcomes over a full year of cards rather than a lucky or unlucky stretch. If your simulated 5th-percentile outcome is a bankroll wipeout, your sizing is too aggressive regardless of how good your model’s edge looks on paper. The same underlying math behind tournament chip-stack risk sizing in poker applies here: variance management matters as much as edge-finding once real money is on the table.
What Builders and Bettors Get Wrong
The most common mistake is trusting career-average stats over rolling recent form, which quietly bakes in a fighter’s past self and misses obvious decline or improvement. The second is skipping chronological splits and accidentally training on data that wouldn’t have existed on fight night, a leak that inflates every backtest number until real money proves it wrong. Start simple: clean pipeline, honest calibration, a modest ensemble, and a public record of your own results measured against the closing line.
— Manuel
Get a Verified MMA Betting Model Without Building One Yourself
Building and maintaining the pipeline described above, data scraping, feature engineering, ensemble training, and calibration checks, takes real engineering time most bettors don’t have. Manny’s Variety runs that infrastructure for you, publishing every MMA and UFC pick in a permanent, publicly graded archive rather than a curated highlight reel.
You can check the claims yourself before committing to anything: browse the results tracker for graded history, read how the AI engines generate picks, and look at a sample matchup breakdown to see how probability outputs turn into an actual betting recommendation. Start with the Free plan to see daily picks in action, or move directly to Core or Elite plans for full access to props, parlays, and fantasy tools. Check the pricing page for details and pick the tier that matches how much of the model’s output you want to use.
Sources
FAQ
What Is an MMA Betting Model?
An MMA betting model is a machine learning system, typically built on XGBoost, LightGBM, or a stacked ensemble, that outputs calibrated probabilities for fight outcomes like moneyline, method of victory, and round. The goal is a probability you can compare against sportsbook odds to spot mispriced bets, not a guaranteed winner pick.
How Accurate Are MMA Prediction Models?
Well-built classifiers reach mid-to-high 60s accuracy on held-out fights, per the CageMetrics methodology, and one documented ensemble reported roughly 78% accuracy and 0.87 ROC-AUC on its own test set. Accuracy alone is misleading, though; log loss and Brier score matter more for actual betting decisions.
Can an MMA Betting Model Beat the Sportsbook Long Term?
Models rarely beat the market outright on favorites, since sportsbook lines already price in most public information. The realistic use case is finding undercard fights, props, and underdogs where the model’s edge exceeds the implied probability by a meaningful margin, then applying disciplined bankroll rules.
Does Manny’s Variety Publish Its MMA Betting Model Results?
Yes. Manny’s Variety maintains a permanent, publicly graded archive of every MMA pick alongside a results tracker showing performance over time, rather than a curated sample of only its wins.
How Much Should I Bet Using an MMA Prediction Model?
Most disciplined bettors flat-stake 1 to 3% of their bankroll per fight, or use a fractional Kelly criterion scaled down to reduce variance. Cap total exposure across an entire card at roughly 5 to 10% of bankroll, regardless of how many bets the model flags as favorable.